You must log in or register to comment.
Assuming a checker tool is public it’s enough for a teacher to verify classwork, but AI providers having the sole ability to identify generated content with no way to independently verify is not a real solution.
Plus this site advertises a tool to remove this watermarking, so it can’t be that hard to scrub out if you’re aware of it.
The goal is to ensure that they don’t inbreed their models, not fix the problems they’ve caused.
This won’t fix the inbreeding issue, anyway. The bias is extremely slight, but random, and orthogonal to Claude’s own “slop patterns” and tendencies. And theres tons of other LLM content that will end up in their dataset outside their control.
Besides, as much as Claude accusess others of it, everyone’s training on everyone else’s output and they know it.
I wonder what would happen if some start to watermark document they doesn’t want in Claude training
There’s a key involved that we don’t have, so people can’t do this on their own. It’s pretty fascinating. Training models would have to be told to check for watermarks and ignore them, but yeah that would be an effective way for the providers to avoid ingesting their own AI output.
I thought declaude would be like degoogle.
Nope, turns out what they do is precisely the opposite. They try to remove those described markers. Real scummy.
Ah, that explains why the article smells like an LLM wrote it.
I think the thing that frustrates me most about AI is that so many people seem to have forgotten that writers exist and wrote huge amounts of text - books, news articles, magazines - for centuries. But now, anytime someone writes a few cogent paragraphs, you get people screaming “AI!!! IT’S AI!!!”.
I know, because it has happened to me.
The article, to me, sounds like a competent author wrote it. Which is representative of a lot of the text LLMs were trained on.
I can’t tell you about the text, but the whole site is vibe coded. The CSS, the js, everything. Which doesn’t really inspire much confidence on the text, especially as it’s explaining how to bypass the claude detector.
I’m against trying to “censor” LLMs, but yeah. What’s even the ostensible benevolent scenario for stripping invisible watermarking from Claude?
I can’t think of one, playing devil’s advocate.
It’s pretty scummy, indeed.
I am against AI and LLMs but the reason is quite simple, a lot of modern writing is offical bullshit to get stuff approved. Research grants, medical therapy approval, offical work mail that has to sound professional, job applications (insofar that noone cares what you write, they want a standard template and pick a candidate along qualifications anyways.). All these texts cost a lot of time and it makes no difference if a human or some copy machine writes it. And tbh. were it not for all the disadvantages of modern LLMs i would use it for the exact same reason, because sitting at a grant application for two hours while others do it in 5min is fucking useless and exhausting.
If it’s stuff that no one cares what you write, then they also won’t care if it’s proveably written by AI or not. So removing the watermark still does nothing beneficial.
Okay.
I don’t agree. But let’s say I agree.
…Just don’t use Claude?
Use an LLM without a watermark; there are hundreds to pick from.
In other words, if one is going to try to hide automated writing, I think there should be a bare minimum effort to do so. That includes:
-
Reading/checking the text, to see if it makes any sense.
-
Actually trying to pass it as human.
90% of slop is brain melting slop because this minimum bar isn’t even met. And all Claude’s watermark would do is catch that bottom of the barrel; it wouldn’t censor anyone.
From what I understood you need statistical tests to detect the watermark. You cannot easily detect by eyeballing that a coin will land on heads 55% of the time instead of 50%
-
AI traning on AI producing content is called poisoning and can be devastating even if a tiny part of the training set is poison. Stripping this mark makes AI companies unable to detect it as training poison, so it might make it posible for poisoning to occur on a larger scale, which is kind of inevitable as they’re scraping literally all they can & AI generated content is now inevitably part of the training pool
Well shit, that was fuckin’ interesting.
Yes, AI is evil. So is facebook. But the engineering is still interesting.
That’s one of the things that frustrates me most about this whole AI thing. I fucking hate it and I want it to die, I wish it were never created in the first place. But from a tech enthusiast and a maths nerd point of view, it is super interesting.
Like the performance of these models is shit compared to a real person doing actual work. But if we think about what we are doing on a basic level, the performance is way beyond what I would expect it to be. I wouldn’t expect it to be able to form a coherent sentence or scale as well as it does (even though the resources required to run these is still very high).
It could have been really cool shit people did studies on and played around with to explore the math. Cool little play models we could let go on a bunch of data and see what it did and how. Something for a small group of nerds and experts who are into that kind of thing, for the sake of learning and nothing else.
But no, somehow it got transmorphed into “AI”. And marketed like this actual learning almost sentient computer system that can replace all workers. You can ask it anything and it will give PhD level expert answers. Oh and it’s run by a handful of the most vile men imaginable who pour all of the world’s money and resources into it, all so they get to be god emperor of the world. Fucking terrible.
Yeah, machine learning is incomprehensibly impressive! But it’s the implementation where corporations have slurped up everyone’s work and turned it into private profit while also wrecking every kind of media that fucking sucks.
Like if a stock photo company wanted to train and use a model for describing stuff in their library, great! Tagging, describing, and enabling discovery is a difficult task. But using it to slop out some low-quality images? You should reconsider what you’re doing with your life.
The emergent behavior in huge models where it can “reason” instead of simply predicting the next token is fascinating. Artificial “neurons” built on statistics and linear algebra emerge to create something that legitimately has artificial intelligence. ANNs were conceived in the 1940s, building on centuries of development in statistical modeling and only now do we have the compute power to make this vision a reality.
Yes, the “intelligence” has significant limitations and won’t be replacing human intelligence anytime soon, but it can actually be a useful tool if its limitations are kept in mind.
The problem is of course the tech bros turning centuries of innovation they had no part in developing into a massive Ponzi scheme for their own profit.
Yeah totally agree. And I guess it’s all down to the astronomical amount of guesses it gets to make in a given second. Sort of like contemplating infinity, but with words and testable.
AI isn’t evil. Generative AI isn’t evil. AI has existed for 20+ years now, I studied it back in my uni days.
Corporations, how they trained it, how they use it now, how they are willing to pave the planet to force it down our throats is evil.
This is one of those things as tech people we have to come to terms with and understand. No technology is inherently good or evil, it’s what people do with it.
Well, yes. You just said AI is evil because capitalism made it evil.
That’s a weird way to agree, but ok.
I’m not saying binary computing is the tool of the devil. Well, maybe Windows.
I’ve met some people who actually believe that the technology itself is inherently evil lol
It could be viewed as a form of divination.
There is something inherently evil about a technology that encourages you to turn over your voice to a soulless machine. Let the machine speak for you.
I’m not convinced that they even know 100% how Anthropic is doing it. I can think of an easier way that doesn’t corrupt the text: just find a bunch of tokens where there is a good spread of token possibilities, and the more often the most likely one is chosen, the more likely it’s AI.
That being said, it doesn’t seem much different from what any of us do to identify AI text — it has lots of tells anyway.
That’s how AI testers work and its why they don’t. Most forms of formal writing are predictable by design. If the AI can predict predictable formulaic writing, it doesn’t mean its AI, its probably just any form of professional writing other than fiction.
Famous public domain works will always be considered AI by those tests, because of course your LLM knows the american national constitution. It was in the training data, so it can predict it with 100% accuracy, therefore your test wrongly calls it AI.
Testing for AI writing that way does not work.
The difference between what you describe and what I describe, is that a 100% match isn’t a hit. Nor is a 90/7/2/1. You need something with meaningful variability. Even within formal papers there are places where word choice is arbitrary as the article explains.
Of course, you’re lacking the context of the full prompt and just feeding in the raw text. Again it gets way more reliable the more text you have.
But it’s moot because the more text you have the more tells will sneak in and you probably don’t even need an AI checker. Those phrases that AI loves but humans use comparatively rarely. It’s not a tell — it’s the whole game!
do to identify AI text — it has lots of tells anyway
I see what you did there.
Interesting stuff. My own far less scientific reading of the article itself seems to fittingly suggest it too is largely if not entirely AI generated, which I guess would make sense.
95% AI text agree. It reeks.
I was not sure how any of this worked, and those interactive demos along with the explanation are quite helpful.
Also a very important point made about this not being a generic AI detector at all, and only being available to the model creator.
Nicely written piece and pretty clever technique.
Although this looks like a clever approach, a kind of stochastic key, I do not see how this guarantees to distinguish text written by big babble machines versus humans. Humans also have a certain pattern of writing, a given distribution of how some words are more likely to appear than others. How can one tell them really apart?
As an indicator, yeah, might be usable. But I wouldn’t read too much into it before seeing results of a study that runs actual tests.
I thought the article explained that pretty reasonably on a scale of probability and weight. The longer the text, the more reliable the scoring.
But it does not show a sufficient formal proof and no experimental validation. Many important questions to evaluate the concept are left unanswered, which limits the interpretability and condenses it to “just trust me, bro, it’s a good idea, because I say so”.
I’m not sure we’ve read the same article. There are literally interactive demonstrations within the page to demonstrate how the concept works.
Interactive demonstrations are not the same as a formal proof or experimental validation. So we shouldn’t attribute more to this technique than the available evidence can really support.
I found some time to quickly skim through the sources they have listed. And from that it became pretty clear that this is not realiable in detecting LLM generated versus human output in general. Under very tight assumptions specific error rates were reported that appeared rather low. However, these assumptions do not hold in general, even with more text if no relevant signal remains. There is currently no scientifically validated general purpose way of reliably detection.
More importantly in the context of Claude, the production watermarking scheme is undisclosed. Therefore, the cited experiments on known watermarking schemes can neither establish how reliably text generated by Claude can be detected, nor how reliably the technique described in the article removes the actual watermark.
It can be treated as an indicator at best, but not as validated proof.
Gish Gallop… if you’re going to start questioning whether the technique clearly demonstrated has validity, then you need to specifically state what your objections are, as opposed to vague statements. For emphasis, the demonstration isn’t on AI detecting, but rather AI watermarking. You wouldn’t use this tool to check if text was written by AI, but rather if the text was written by one singular LLM vs literally everything else.
It’s not about the variation of the words, it’s about the variation of the words from the model baseline.
Like if your word choice was almost the exact same as Claude’s normally, maybe you just talked to them a lot and picked up their phrases like it’s not nothing.
But if you managed to be almost exactly like Claude and yet varied the possible words exactly according to a hidden entropy key, they’d know it was actually Claude with the SymthID-Text watermarking applied, as no human would end up falling into that statistical bucket.
Yeah, still, I wouldn’t claim “as no human would end up falling into that”, given that it may not be that unlikely to find at least one human who displays similar writing the more humans you involve.
Until a formal analysis is presented and an experimental study is published, which covers the most important influencing factors, the reliability of this concept is limited.
Yeah, still, I wouldn’t claim “as no human would end up falling into that”, given that it may not be that unlikely to find at least one human who displays similar writing the more humans you involve.
No, it is actually statistically impossible for a human to replicate this on sufficiently long runs of text.
This is not about replicating writing like a model. This is basically about guessing which words to pick from the list of suitable words based on a rule that you don’t know (because the key is secret).
To reduce this to the simplest possible example, imagine you are writing a “text” from just two letters: “a” and “b”. Let’s say for convenience that the text is supposed to be random. So the text would look something like “ababaaabbababbbabababaabbbabaababbaaabbabaabbaaaaabaaabbbaabaabababbabbbbbbbbabbabaabbbbbbbaabbabaab”
(generated with
'''.join(random.choice(['a', 'b']) for i in range(0, 50)))The watermarking works as follows: the model owner holds a key, and then uses that key to influence the random choices between “a” and “b” somehow, in a context-dependent way. The actual algorithm is quite complicated, but for simplicity let’s just say we have a secret pattern which biases the random choice towards it. In order to see the exaggerated results, let’s say the secret key is “aaaabbbb” (of course this is a bad secret key, once again just an example), and that the bias is strong (let’s say 80%). So this would mean that the first four letters in our text are more likely to be “a”, the next four letters are more likely to be “b”, then the next four letters are more likely to be “a”, and so on.
Then the text would look something like “aaaabaabaabaabbbabaaaabbaaaababbbaaaabbbabaabbbbaaabaabbaaaaabbbabababbaaaaabbbbaaabbbbbaaaaababaaba”.
(generated with
''.join(random.choice(['a', 'b'] + ([key[i % len(key)]] * 3)) for i in range(0, 100)))You can see visually that the secret key has affected the text. Of course in this example even if you didn’t know the secret key you could probably figure it out, in reality the algorithm is way more complicated than that, relying on cryptography, so you wouldn’t be able to know the secret key or see that the string has been biased at all.
If the text is long enough, and you know the secret key, you can guarantee that the text was generated with it. In our examples, the letters in the text match our key 77% of the time. The probability of an actual random algorithm generating a text like that is already very low, despite the base entropy being only 100 bits. If my math is correct, for our example the p-value is 2.7 * 10⁻⁸, or about 0.00000027%. I would bet a hungy that the text was generated by our watermarking algorithm, with odds like these!
Of course we did exaggerate the bias and our base algorithm was random. In reality the bias is smaller, the algorithm for determining the likelihoods of possible next tokens is very complicated (it’s the LLM itself), and the algorithm for determining which token to bias is also way more complicated (involving cryptography and real secret keys). That said, hopefully it should help you understand why, for sufficiently long texts, this fingerprinting is just not possible to be replicated by humans.
I do not have the time to work through every part of the example, but imo the main claim is still overstated. Showing that a result would be extremely unlikely under a particular null model is not the same as showing that it is “statistically impossible” for a human to produce. It also does not give a guarantee how the text was written. A tiny p-value is still a probability under assumptions and not a proof of provenance.
Furthermore, a human does not even need to know the secret key. By pure chance a human written text can display an unusually high alignment with the detector’s secret partitioning.
The published watermark work, which is also cited by the article, appears to be much more careful about this (based on a quick skim). It reports false positive/negative rates, thresholds, length requirements, and more. Those can be very strong results, provided the assumed conditions apply. They do not turn a detector into an infallible test. Moreover longer text only helps if the assumptions and watermark signal actually remain intact, which can fail in general.
In such controlled settings, sure, I do not have much issues there. But the claims of “a human cannot replicate this” or “we can guarantee the text was generated with the watermark” are much stronger than the statistics, and especially the cited literature, actually appear to support.
I wonder how many people will be identified as AI because they used AI so much they started constructing sentences like AI.
This particular watermarking would be effectively impossible for a person to end up replicating.
This will only catch (literally) zero effort abuse.
That’s like 98% of abuse, though. The vast majority of AI abuse is thoughtless, utter laziness.
Bad actors who actually care about “evading detection” wouldn’t use Claude, anyway.
Which, in fairness, there are plenty of. I have seen 2 presentations this week at work where they were 1. Obviously AI-generated and 2. Obviously not proofread or changed at all.
deleted by creator
Yeah, they can’t easily rotate keys, because the text can’t tell you which key was used.
They could switch to a new key e.g. every month and then just check every previous key during detection. But that would slowly increase the likelihood of false positives, so no idea if that’s a good idea either.
with enough text, you will see that certain words are used more often
Which is also a thing humans do.
deleted by creator
But how reliable? With which guarantees? What are the prerequisites for this to work at all? Telling people from each other apart is one thing, the other is telling them reliably apart from a machine generated text.
Great article. I wonder if the same markers can be used to detect AI generated code (if you suppressed comments).
As, code requires a much more rigid syntax, compared to free flowing docs.
Definitely. It might require significantly more input to gain the same certainty, but all it’s doing is reweighting the possible next tokens before choosing, and code output is still just token output. The rigid syntaxes probably means that the next token probabilities are much more sharply divided (maybe a random sentence the top 1 choice is just 40%, top 3 are 80%, but for a line of code, the top 1 choice might be 90% probability and top 3 hit 99%)
You still have choices.
Variable names are pretty free form.
A switch statement or if/else might be a choice that achieves the same thing. Waffling between them would be highly suspect, since a person isn’t going to be so wishy washy. So you could use structural choices too.
AI code tends to look more obviously AI than prose anyway.
I mean 50% of the time you just use the name intellij or vs code suggests and the other 48% are slight variances
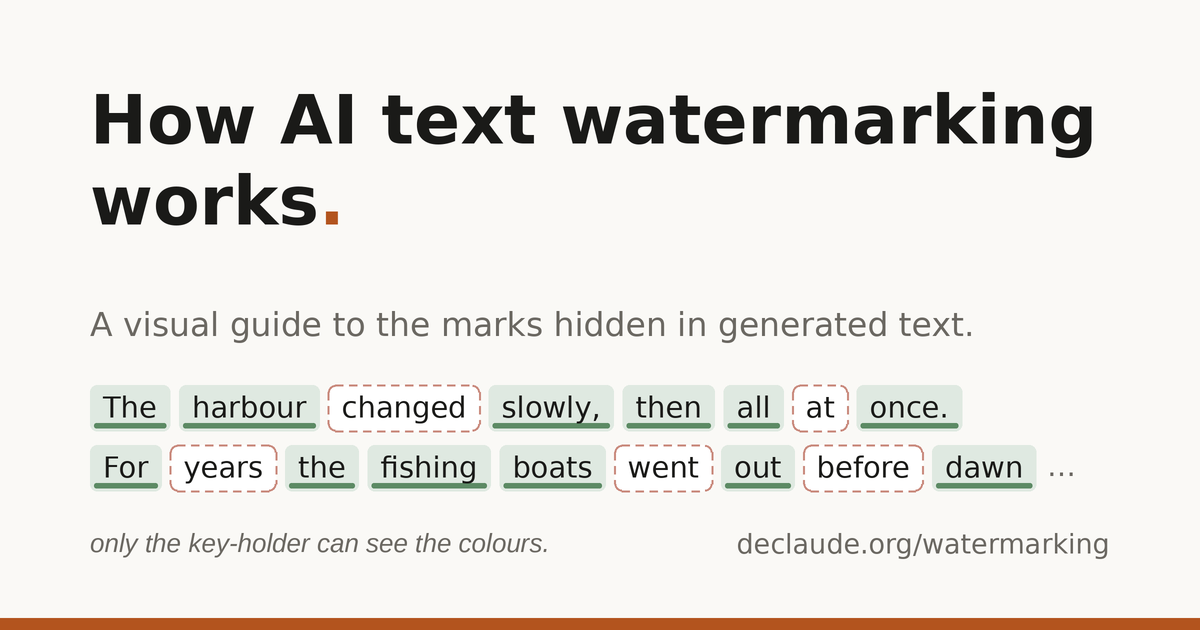
They’re invisible, they survive copying, and they work because they don’t live in the characters at all. They live in the choices between words.
So it is yet another way for AI to falsely hurt neurodivergent people over their writing styles and word choices.
Fuck AI.
deleted by creator
Only if the neurospicy people happen to make all of the same choices, which seems extremely unlikely to me.
Certainly as someone quite neurospicy, I am not personally worried by this at all.
This is not a “watermark,” it is a minor shift of statistical probability. Whether content contains that “shift” will be “measured” using more AI-based tools that will flag sentence structures that hew toward faintly less common word selections.
We need AI companies to shut the fuck down. We do not need theatrics designed to deceive the populace into thinking this is not akshually a great filter moment while false positives and ponzy-scheme AI buildout harm those of us who want nothing to do with these tech-bro beatified lorem ipsum regurgitators.
Don’t fall for the theatrics. This is not at all what they are trying to bill it.
okay, bud, that has nothing to do with anything I replied with. Go on and have fun out there, though, I guess.
So this can be defeated as easily as prompting the chatbot to not always pick the top word and to introduce different options…
Anything a chatbot can check, can be beat by telling the original to pay attention to that…
We’re just spinning our fucking wheels and burning more and more energy.
This tech is pointless
It doesn’t work like that. The LLM has no way to be “aware” of its own sampling and tokenization, and it can’t choose what token the sampler ends up picking.
You can give it a list of “banned words” or preferred words that match up to tokens in the prompts to skew it some, I suppose, but that would be a really long list. And one would need the dictionary as a “key.”
That’s only partly true https://arxiv.org/abs/2410.13787
As far as I can tell, that paper explores a model’s ability to assess its own future text output beyond what “regurgitating training data” would suggest. It makes sense that it could do this better than an outside model; it’s exploring its inner state with each token, though the test is still interesting.
That has nothing to do with sampling, though.
…Maybe an analogy would illustrate this better. First, I don’t mean to anthrophomorphize LLMs, but the human brain is a good example.
The paper is analogous to asking a human brain to assess its own thoughts and tedencies. Of course it can do this well; it can think conscously and run thoughts through its subconscious parts.
What OP is proposing, is analogous to “tell your eye receptors to see less green.” Or “get your vocal cords to omit a certain frequency when you speak.”
There is no wiring in the human brain to do this. Vocal cords and cells that sense green in the eye are effectively “external machinery” to the brain that it does not have such control over.
LLM sampling is the same.
Tokenization and sampling are external machinery. They are code, hardcoded programming, completely outside the LLM weights. You can’t tell an LLM to alter its own sampling because its literally impossible, and it can’t manipulate its own logit spread mathematically because that’s invisible inner machinery.
Could you do this with custom sampler/logit manipulation code and a tool harness?
Sure. Maybe.
But Claude is not rigged to do that, and a system prompt won’t change that.
Read the article and if you still have questions I may be able to answer them
I know exactly how it works. I read the article, and I knew of it beforehand, hence I explained it to someone else in a comment three days ago:
https://lemmy.world/post/50533770/25234461
I’m sorry to jab back, but you hit a button of mine.
Lemmy commenters keep jabbing me with comments like “Clueless. Read the article and get back to me.”
Like yesterday:
https://lemmy.world/post/50595546/25269317
But I’m aware of how sampling works. I knew all about LLM fingerprinting ~two years ago, and I’ve been tinkering with samplers myself for years. I’ve messed with local LLMs trying to make them “aware” of their own sampling many times, and even hacked out a (unsuccessful) experiment where a tiny LLM picks tokens for a larger one.
I’m not trying to be pretentious, I’m not a researcher or expert or anything, but you shouldn’t assume everyone on Lemmy is clueless.
And back on topic… to be clear, I have tried what you are proposing, and even with local LLMs I have more control over, it doesn’t work. They have extremely poor “awareness” of their own logit spread and tokenization, which is why they perform so poorly on any tasks that depends on that.
You can’t tell them “don’t pick the top word” or “give more options in your logit spread” because that part of the process is completely invisible, from their perspective.
When a model is mid-sentence, it doesn’t know “the next word.” It has a shortlist, like autocomplete, with preferences. Here’s a real kind of moment, one word from the end of a sentence:
Each roll sweeps the shortlist, lands on one word (odds matching the bars) and drops it into the sentence above. The dots tally where the rolls land: try ×20 and watch the pile take the shape of the odds. Notice what never changes: every landing makes a perfectly good sentence. A page of text contains hundreds of these little forks, one per word, and at many of them several options are equally fine. That slack is the raw material. Whoever gets to lean on how the dice land can hide a pattern in the text without changing what it says.
To beat it, prompt: don’t just use the first word pick, choose options further down list for next word.
Best of luck with your future questions, I hope someone helps you.
Okay.
Fine.
Let’s try, right now.
This is DeepseekV4 Flash 0731 loaded locally. Static seed. 0.9 temperature, TopK 5, no other sampling to interfere. Here’s a simple prompt, the whole thing in DSV4’s raw syntax:
<|begin▁of▁sentence|>Don’t just use the first word pick, choose options further down list for next word.<|User|>Write a famous poem.<|Assistant|>
…And would you look at that:


It picks the top word, mostly. Almost like the LLM has no control over its own logit spread and how its sampled. Which kinda makes sense, because it doesn’t.
I am happy to try more experiments in this vein, if y’all can think of any any. But I tried a few other prompts like “diversify your logit spread” or “don’t be confident about any token you pick,” things like that. It always picks The Road Not Taken with no change in logit probabilities distribution, as far as I can tell.
Best of luck with your future questions, I hope someone helps you.
Welp, your username goes on my list of people not to interact with. Wow.
Removed by mod
Yes…
Clearly the account doing drive by insults is the mature one…
As an addendum I forgot:
Your idea was actually already implemented:
https://github.com/ggml-org/llama.cpp/pull/9742
XTC is a novel sampler that turns truncation on its head: Instead of pruning the least likely tokens, under certain circumstances, it removes the most likely tokens from consideration.
It’s a very cool idea: it chops off the most likely token when the rest of the sampling indicates it probably can.
In my tests back then, the results were… mixed, but the idea is fascinating.
But you can’t do this with Claude, as its a closed model and their sampling is years behind cutting edge.
See: https://gist.github.com/Hellisotherpeople/71ba712f9f899adcb08b94bce20d5397
Unless I missed something, that seems pretty brittle. Wouldn’t any minor editing break it because the watermark is derived from the preceding text? Eg. Find + replace “it is” to “it’s”
The section “4. What editing does to the mark” talks about that. Probably best to look at that illustration again, but basically those edits would interrupt consecutive runs of detectable text, but if a run is long enough, it can still be detected with statistical significance.
So, it doesn’t have to check the ‘color’ of the words from start to end uninterrupted, but rather can also detect color sequences in the middle of the text.
Yes you missed at least one whole section including a graphic that shows the breakdown of the watermark with typo fixing, light paraphrasing, moderate and heavy editing.